Local LLM routing on a GEEKOM A9 Max mini PC
I built a local agent factory on one mini PC. Every active agent runs on the local model, on the A9 itself. Here's how it works and the calls I made.
How it works
The A9 has an AMD Ryzen AI 9 HX 370 with integrated Radeon 890M graphics and 128 GB of RAM. It runs Ubuntu, with a BIOS and pin configuration I tuned for local inference.
In the BIOS I turned on Above 4G Decoding and Resizable BAR, set the Performance power profile and set an aggressive fan curve.
An integrated GPU has no memory of its own. I cut its fixed reservation in the BIOS to 512 MB and raised the shared memory it can borrow to 128 GiB, so the model loads onto the GPU from system memory. I also limited inference to part of the CPU's threads and run it at lower priority, so the desktop stays responsive while agents work.
The model is Qwen 3.8 Flash-Next, a 177B-parameter mixture-of-experts model, 4-bit quantized. It runs through Ollama on Vulkan with the open-source Mesa RADV driver. I chose Vulkan over ROCm because ROCm only used the small fixed GPU memory and ran slower.
I pin one model for every agent and hold the driver and runtime versions in place. After the GPU crashed under agent load, I rolled the GPU settings back. I only raise them after 48 clean hours and a new benchmark.
Paperclip runs the agent org and its tickets, and Hermes is the agent runtime. I designed the orchestration around one GPU: my orchestrator agent, Hephaestian, takes one assignment, creates exactly one child task for one specialist, waits, checks the result and closes it. It wakes on events, not on a timer.
I set it to stop and escalate on unclear scope, a busy GPU, anything to publish, keys or money. My local agents run under a $0 spend cap. One of the things this stack runs is Presence, the website and social system for MeltingFace.io.
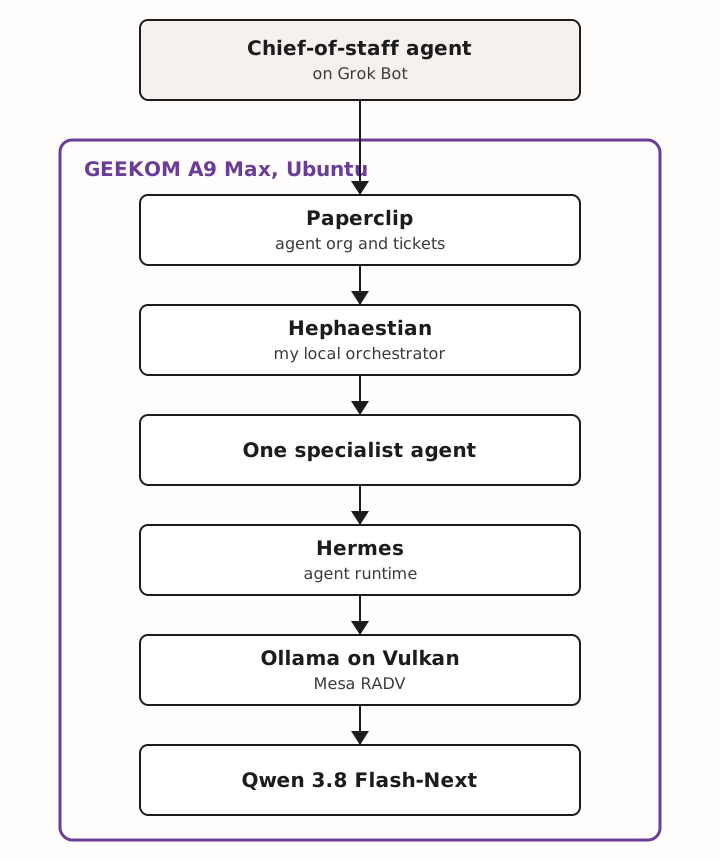
How the diagram reads, box by box:
- Chief-of-staff agent on Grok Bot, arrow to Paperclip (agent org and tickets).
- Paperclip, arrow to Hephaestian (my local orchestrator).
- Hephaestian, arrow to one specialist agent.
- Specialist agent, arrow to Hermes (agent runtime).
- Hermes, arrow to Ollama on Vulkan (Mesa RADV).
- Ollama, arrow to Qwen 3.8 Flash-Next.
- One outer box around Paperclip, Hephaestian, the specialist agent, Hermes, Ollama and the model: GEEKOM A9 Max, Ubuntu.
Built with a team of AI agents under my direction. I set the scope, made the product calls, and nothing shipped without my yes.